Research

Research on making LLM systems more reliable.

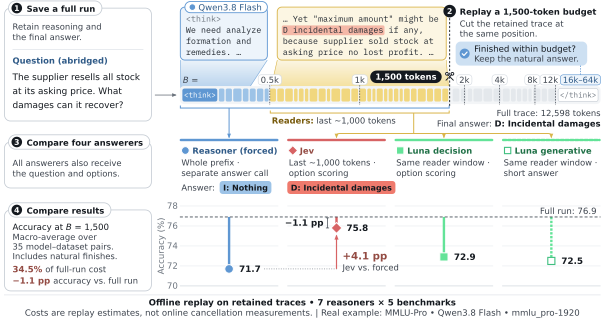
Main figure from “Truncated Reasoning Under a Budget: Evaluating System-1 Models as Decision-Makers” First author

Under review, ACL Rolling Review · Oct 2026

Truncated Reasoning Under a Budget: Evaluating System-1 Models as Decision-Makers

Zhongyin Wang, Zhaoqian Xue, Junting Mu, Haozheng Liu, Ye Yuan, Haolun Wu, Lingyao Li

When a reasoning model is cut off mid-thought, a System-1 decision model can read the partial trace and answer. At a 1,500-token budget it beats forced answering by 4.1 pp, and a learned stopping policy saves 71.3% of the full-run cost for a 0.58 pp accuracy loss.
LLM ReasoningEfficiencyEvaluation
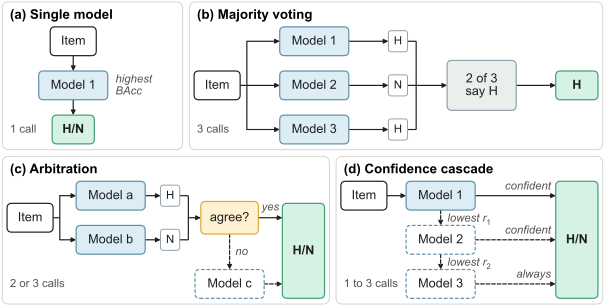
Main figure from “Decision Models as Judges for Hallucination Detection”

Under review, ACL Rolling Review · Oct 2026

Decision Models as Judges for Hallucination Detection

Haozheng Liu, Zhaoqian Xue, Zhongyin Wang, Junting Mu, Zihui Ma, Shuya Feng, Lingyao Li

Can cheap decision models stand in for LLM judges? Across five hallucination types (9,852 items), they match or come close on some types, and a confidence cascade reaches a generative judge's accuracy at 1–3% of its cost — but needs validation before use.

LLM-as-a-JudgeHallucinationCalibration
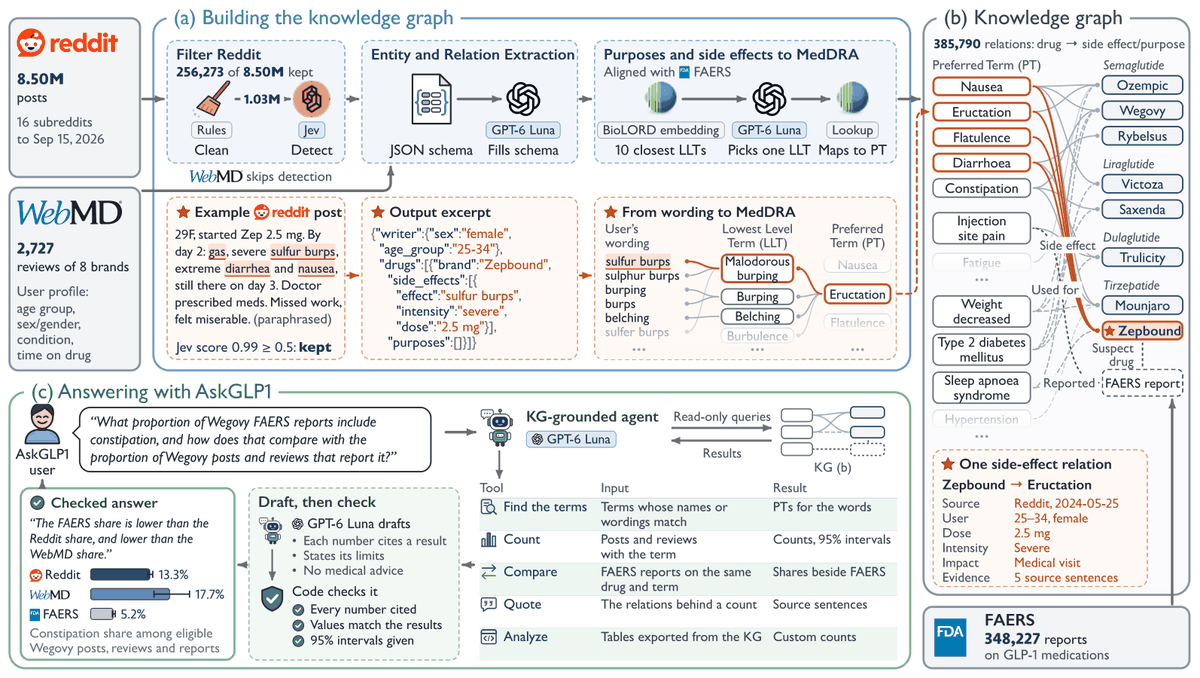
Main figure from “AskGLP1: A Knowledge Graph LLM Agent for Exploring GLP-1 Experience from Online Patient Narratives”

Preprint · Oct 2026

AskGLP1: A Knowledge Graph LLM Agent for Exploring GLP-1 Experience from Online Patient Narratives

Zhaoqian Xue, Anay Somani, Siddhartha Singh, Junting Mu, Zhongyin Wang, Haozheng Liu, Ayesha Khatun, Yeaeun Kwon, Renkai Ma, Siyuan Ma, Zhe He, Danxia Yu, Lingyao Li

A knowledge-graph agent built from 163K Reddit posts and WebMD reviews (385,790 drug–side-effect relations) that answers GLP-1 questions with verifiable evidence, and shows where patient narratives and FAERS reports diverge.

Knowledge GraphLLM AgentPharmacovigilance
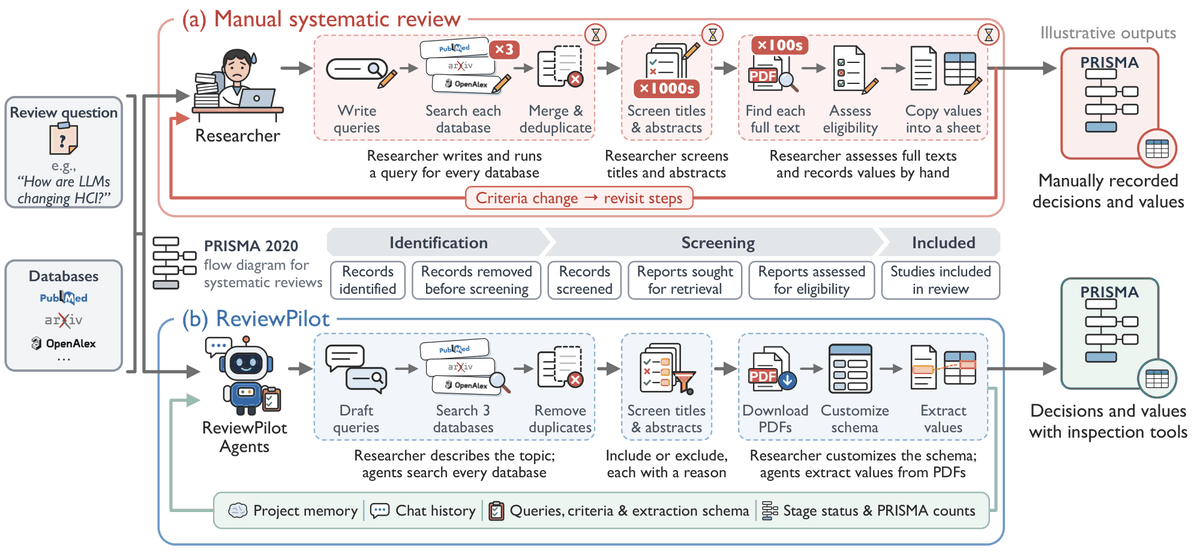
Main figure from “ReviewPilot: A Multi-Agent System for Screening and Data Extraction in Systematic Reviews”

Under review, ACL Rolling Review · Oct 2026

ReviewPilot: A Multi-Agent System for Screening and Data Extraction in Systematic Reviews

Zhaoqian Xue, Shaoze Zhou, Xuexin Li, Junting Mu, Haozheng Liu, Zhongyin Wang, Yichun He, Renkai Ma, Hao Zhou, Sarah Bratt, Siyuan Ma, Chen Chen, Lingyao Li

A conversational multi-agent system that automates the PRISMA workflow. Every screening decision comes with a reason and every extracted value with its source, reaching extraction F1 up to 0.788.

Multi-AgentSystematic ReviewPRISMA